My work in Physical AI focuses on digital twins, simulation and robotics. Building 3D scenes is foundational to that work: they provide a spatial representation of the real world that we can use in simulation. I keep coming back to whether a scene is right for the purpose we want it to serve.
For a layout review, I wanted to edit a 3D scene reconstructed from camera images, add other 3D objects and inspect them together in an editable scene. I built SplatStage to carry that work through editing, export and composition. One failure made the handoff concrete: the editor showed my changes, but the exporter still read the original reconstruction and left those changes out.
Starting again, I would test giving that production job to an agent: prepare the scene for review, preserve the selected edits and return a result I can open and revise. I would still build the tools, checks and application that let me use it. The question is whether letting the agent choose the steps for varied requests saves more development and user effort than the production and review work it adds.
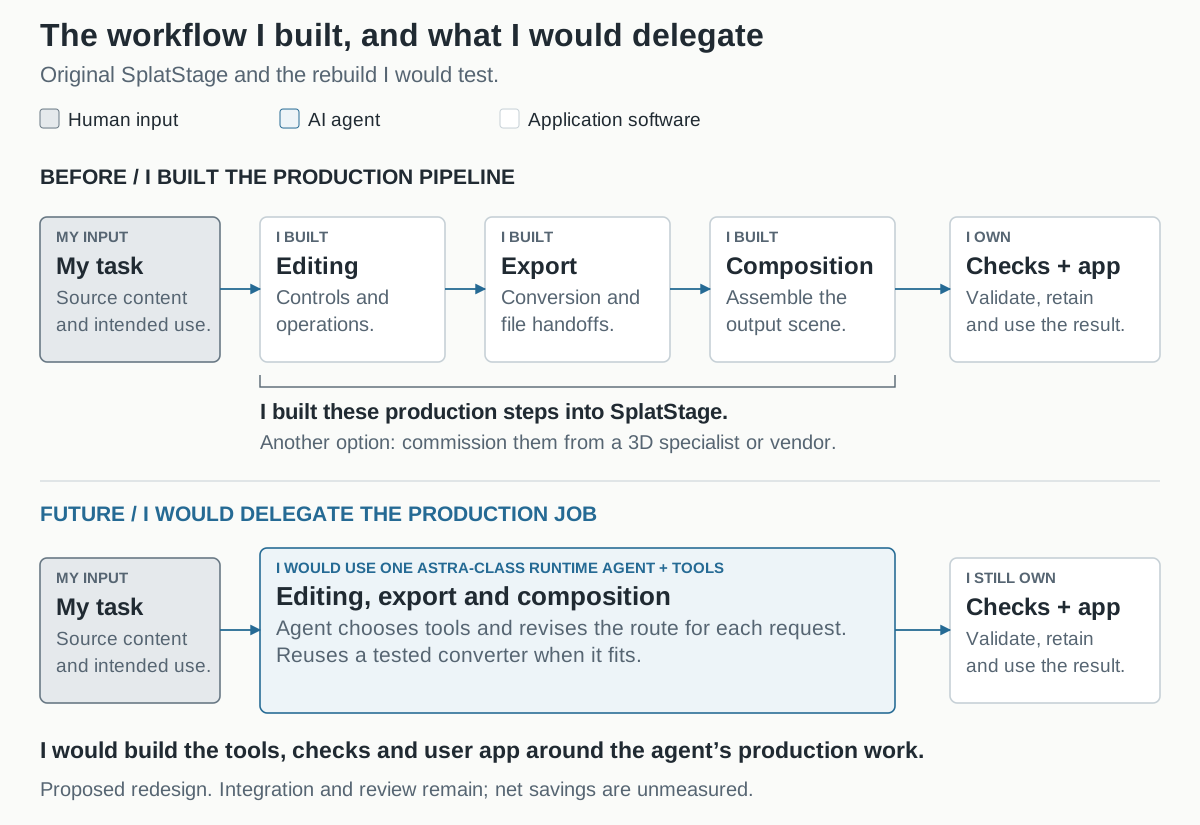
The workflow I built, and what I would delegate
I had already built ReconStudio to turn camera media into a 3D reconstruction. SplatStage addressed the next job: editing that capture and composing it with other assets. The underlying libraries existed. Much of my application work was connecting them and keeping track of which result belonged to which inputs.
Someone who needed that deliverable could commission it from a 3D specialist or vendor, supplying requirements and checking what came back. In the workbench I built, the user chose operations and application code carried them out. It preserved versions and checked the exported result. Supporting a different production route meant extending that software or writing a separate script.
The published demonstrations of GPT-6 Astra, an OpenAI model working as an agent in Codex, show it building an editable Blender scene and moving a version into Unreal Engine. They made me want to test how much of that coordination an agent could handle per request.
My brief to the agent would be: “Prepare this reconstruction for layout review, preserve the selected edits and deliver an editable scene that opens in the destination application.” I would give the agent suitable tools and limits, then let it choose the steps and repair failed handoffs. There is still a workflow; I would no longer prescribe its complete route for every supported request.
An experienced person building the scene can fill gaps using knowledge of the domain and the job. The agent brings learned knowledge too, but I cannot assume it shares my project’s context. I want it to explain consequential assumptions and simplifications, so I can judge whether they fit the intended use. Routine choices within agreed limits should not all need my approval.
I built the three production steps shown above. Commissioning them from a specialist is an alternative; the future row shows the agent assignment I would test. The brief, reusable tools, acceptance checks and user application remain my responsibility. The agent can adapt its tool sequence.
Ordinary scripting is the strongest counterexample. If I export the same representation with the same requirements every day, a tested converter may be cheaper and easier to reproduce. An agent can select that converter without reinventing it.
What the demonstrations establish
The demonstrations and tool comparisons in this article reflect September 2026.
The September 2026 architectural-visualization account on OpenAI’s developer site describes Astra building and revising an editable Blender scene, inspecting renders and transferring an earlier version into Unreal Engine. The account’s author, Thomas Ricouard, describes the direction and feedback he supplied. The work spans scene authoring, scripts, export and application behavior.
The transfer itself, the same kind of handoff that ends my SplatStage assignment, used an export/import pipeline that Astra wrote. That supports delegating the production job, including its implementation. It does not establish that keeping an agent in the runtime beats reusing the resulting software. This is a selected provider account, with no matched earlier-model run or complete intervention ledger.
The accompanying game-development account keeps a useful distinction visible: walking uses the Rapier physics engine, while landing has separate terrain and clearance checks. The agent can coordinate the implementation while a specialist engine performs the numerical work.
This pattern predates Astra. Anthropic’s engineering guide on effective agents distinguishes predefined workflows from agents that direct tool use from feedback, with cost and latency as tradeoffs. The Astra examples make broader spatial assignments worth testing; they do not establish that this architecture is new or that an earlier model could not run it.
What I would still build
Letting an agent choose an exporter would still leave the selected-edit problem to check. I would still need software that preserves the selected revision, checks the saved result and retains its evidence.
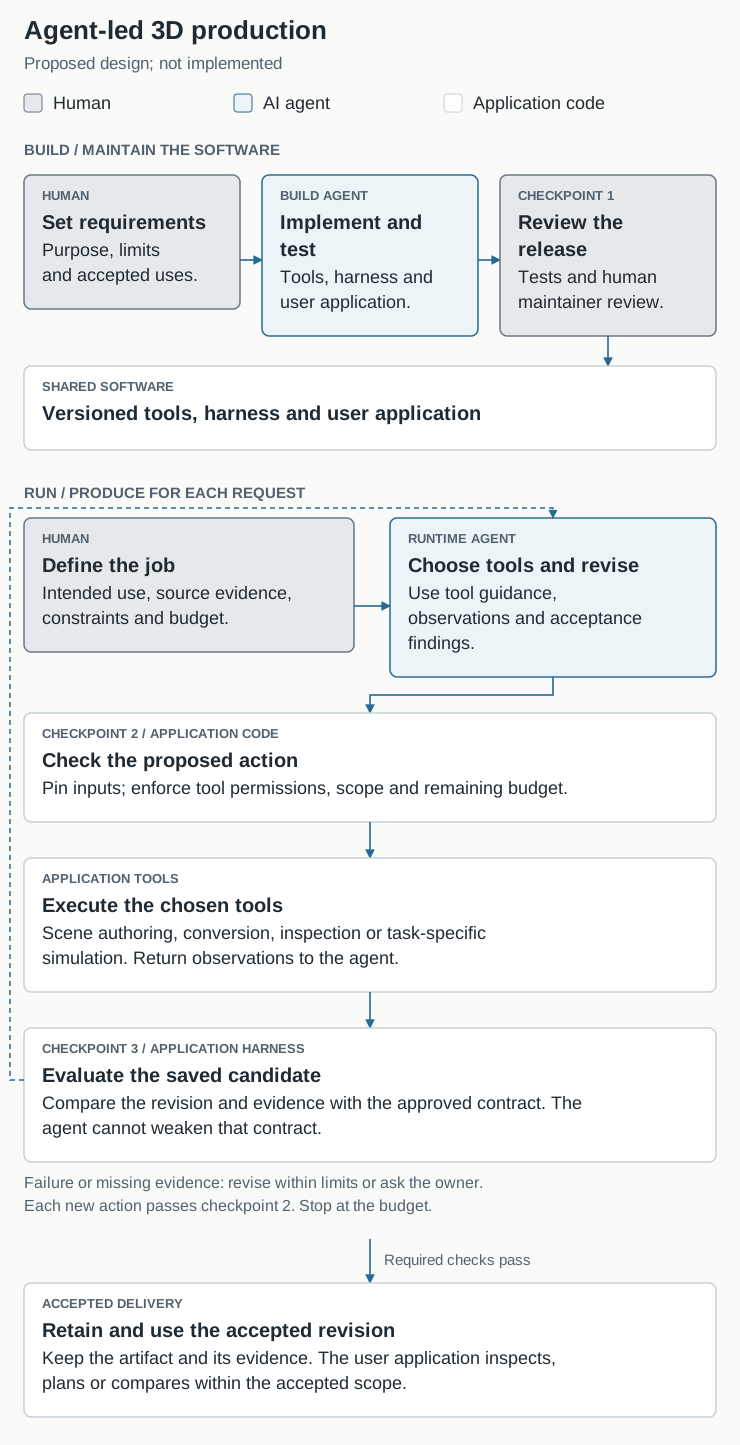
The original SplatStage runtime needed no agent. In the proposed design, a separate coding agent, the build agent in the figure below, would help maintain tools, execution controls, the acceptance harness that checks each result, and the user application. The runtime agent would use those components to produce or revise content for a request. The viewer and simulation engine would continue to execute their own rendering and solver loops.
Proposed SplatStage redesign. Gray: human decisions and review. Blue: build or runtime agents. White: application code, tools and stored evidence. The build agent changes the shared software through release review; the runtime agent chooses a production route for each request. A failed check or missing required evidence keeps the candidate provisional.
The three review checkpoints in the figure have different jobs:
Release review: tests and maintainer review cover changes to the tools, harness and application. A coding agent’s implementation and tests may agree on the same mistake.
Action checks: application code checks the input revision, allowed action and remaining budget before each tool runs. Missing intent or work beyond the authorized scope comes back to the user.
Artifact acceptance: a separate harness checks the saved candidate and its claims against the requested change and intended use. Failure or missing required evidence keeps it provisional; the agent can revise it within its budget or ask for missing input.
Every candidate would take that acceptance route, including imported assets and content generated during development. The producer of a candidate could neither weaken the acceptance rules nor approve its own output. I would retain the source and output versions, tool records, checks and unresolved properties, with the previous accepted version available if the new attempt failed.
A Gaussian field representing the capture, an editable mesh and a simulation scene need different readers and checks. Existing tools already support this work: NVIDIA’s SimReady Foundation, for example, includes asset-profile validation and runtime testing. I would reuse applicable checks and bring their results together around the requested change and intended use. NIST’s work on twin credibility relates verification, validation and uncertainty to intended purpose.
Acceptance for a visual layout does not authorize a contact prediction. Unknown friction may be acceptable for the first use and inadequate for the second. A new use or changed artifact needs its own checks; the third article explains how supported claims, contradictions and unknowns call for different responses. No harness can promise to eliminate all hallucinations.
That leaves useful freedom in the production job. The agent may simplify detail that does not affect the purpose, while surfacing choices that change what the scene can support. If a proposed shortcut conflicts with an explicit requirement, I need to agree a change to the brief before accepting it.
The next articles use an independently designed packaging cell, where cartons pass through sealing and labeling before reaching a pallet. Its dimensions are illustrative; it does not represent a surveyed plant. Moving that pallet invalidates its old clearance result, the check that it stayed out of a reserved aisle. The requested change and acceptance requirements need a separate record from the implementation, a contract, so an agent cannot quietly make its work pass by weakening the requirement. Adding operational data or simulation would still require trustworthy measurements and a model suited to the question.
I would evaluate the harness itself with valid, invalid and incomplete cases, tracking false acceptance, false rejection and overlooked missing evidence. The unchanged-scene case in the packaging review, a scene without the requested pallet move, passed the original geometry checks because they never tested whether the requested edit happened. A more elaborate harness with the same omission would fail in the same way.
I have since built and tested the acceptance component as Scene Acceptance on GitHub. Release 0.5 adds brief preparation, which proposes checks from a written brief, and optional visual review to the contract-based checks. The full SplatStage runtime redesign remains unbuilt, and I have not measured whether it saves work through acceptance.
Count the work through acceptance
A first render is too early to stop the clock. I want to count the work of describing the requirement, producing the artifact, finding discrepancies, correcting them and accepting the saved result. I would then introduce a changed requirement. A workflow that is quick to create but expensive to adapt may be a poor fit for the occasional, changing work that made the general agent attractive.
There is reason to measure instead of trusting the impression of speed. METR’s randomized study of early-2025 coding tools found that 16 experienced open-source developers took 19% longer across 246 tasks when allowed those tools. Its February 2026 follow-up points toward more benefit from later tools, while explaining why selection effects and time measurement make the size of that benefit unreliable. Neither study measures Astra doing this spatial work.
A comparison needs the same task, assets and acceptance criteria, and must count human attention as well as runtime and inference cost. Giving one approach better tools and attributing the whole difference to its model would answer the wrong question.
For an application I already own, its construction cost has been paid. Replacement must justify itself against future maintenance, change effort and switching cost. For a new workflow, avoided development is available to count. Those are different decisions.
If I were building SplatStage in September 2026
Scroll sideways for more columns.
Work
My September 2026 choice
What changes
Produce or revise 3D content
Agent does the job per request, choosing the tools and steps.
Avoid building a dedicated workflow for every variant.
Run a stable, repeated operation
Agent helps build a reusable tool, called whenever it fits.
Keep tested converters where repetition justifies maintaining them.
Check and retain the result
Agent helps build the harness and version store. Checks run independently on every candidate.
Keep acceptance and accepted artifacts under application control.
Help the user inspect, plan or decide
Agent helps build the user application.
Focus development on what the user does with the content.
I would start the comparison with the exporter/checkpoint problem: carry a selected edit through export and destination readback, reopening the result in the destination application, then change the edit or destination and repeat. I would compare the runtime agent with a small script and the existing application, using the same inputs and acceptance criteria. Harness development belongs in the initial cost; inference, corrections and review belong in the cost per accepted result.
Disclaimer: The views and opinions expressed in this account are those of my own and do not represent those of my employer, NVIDIA.