A 3D scene can support a layout discussion, explain a process or provide input to a simulation. Each use depends on different parts being right. When an agent delivers one, I need to decide whether it fits the job I asked for.
I built Scene Acceptance, an acceptance harness, to run selected checks on a saved OpenUSD (USD) scene and keep the requirements, findings and open questions together. I want its report to tell me what happens next: repair the scene, supply missing evidence, or settle a decision the brief left open.
An earlier factory animation showed me why I wanted that review. In my first press-shop build, a transfer arm would compress as it moved a part. I noticed this at some machines; elsewhere, the scene looked reasonably correct to me. The part moved through the demo while the arm changed length.
I had not asked for a physically accurate simulation. I also had not asked for a collapsible arm. For the presentation I wanted, that approximation was not acceptable. The later repair replaced the stretching animation with fixed-length links. The visible result shows what changed; it does not establish why the agent used that approximation.
The first six seconds show the arm on the right compressing; the rest shows the fixed-length repair. Cropped RTX recordings at their original playback speeds, with different cameras and a slower cycle after the repair. Still view · Observation and capture details.
I realized I was accepting more than a finished scene. I was also accepting decisions the agent had made while getting there. An agent can keep a task moving by choosing defaults, resolving ambiguity or deciding that an approximation is sufficient, and I want a chance to inspect those choices before I rely on the result.
I do not want to prescribe every production step. I want the agent to have room to solve the task, with consequential choices made visible enough to review. A declared approximation can be acceptable for a particular use. An explicit requirement miss still needs a repair or an agreed change to the requirement.
The job decides what I need to check. A simplified factory scene may be fine for explaining a layout. Checking how its equipment moves needs evidence about motion and connections, and predicting behavior under load needs a suitable physical model with justified parameters. For the transfer arm, I would now make constant link length an explicit condition and check it through the motion. I found the original problem by watching the demo; no harness check was involved.
Changing the arm’s length could affect an assessment of its reach or the space it moves through, even if it carries a part between the intended endpoints. Those would be additional uses to assess, not conclusions established by the repaired animation.
A coding assistant implemented the harness and ran the studies below under my direction. The recorded experiments keep their original checks and results.
One panel, a width failure and two missing views
A separate panel test shows how the harness turns a brief, the job description, into measurements and requests for evidence. The agreed targets and review questions form its acceptance scope.
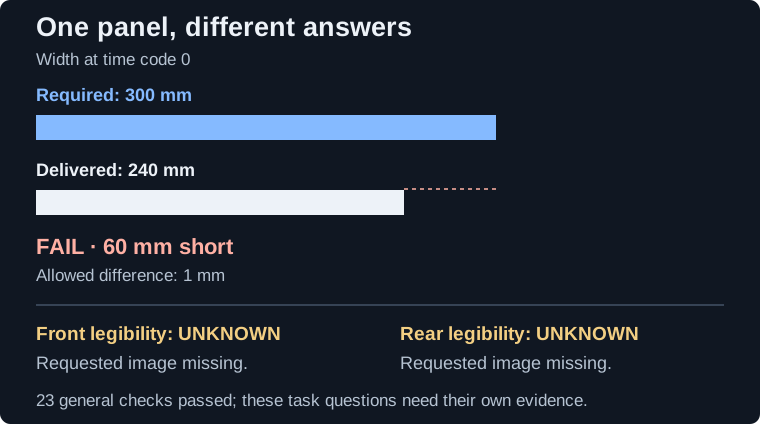
In one test, the brief asked for a panel measuring 0.30 × 0.16 × 0 m within 0.001 m tolerance, with a label legible from separate front and rear views. The existing scene was small: seven prims (USD objects), including one mesh and one material, with no animation or rigid bodies.
An optional interpreter proposed a dimensions check and two capture requests from the brief. The caller, the software or agent running the harness, still had to review that interpretation. Running the measurements before approval helped with diagnosis, but it could not approve either the mapping or the scene.
Scroll sideways for more columns.
Part of the report
What ran or was requested
Saved result
General delivery policy
27 selected rules; no task dimensions supplied to them.
23 passed. Four had no applicable subjects: rigid bodies, colliders, joints and animated transforms.
Brief: panel dimensions
One bounds comparison on /World/Panel.
FAIL: width 0.24 m instead of 0.30 m, a 60 mm difference against 1 mm tolerance.
Brief: front legibility
Dedicated front capture and visual review.
UNKNOWN: no capture supplied.
Brief: rear legibility
A separate rear capture and visual review.
UNKNOWN: no capture supplied.
Interpretation review
Caller decision on the proposed requirement map.
Pending until the caller approves the map.
The report counts subjects within each rule. Here, four rules had nothing to inspect, so they tell me nothing about motion or physical behavior.
If this panel were used to judge a fit, its smaller width could make the available space appear larger than the requested panel would leave. Here the width was explicit, so the measurement identifies a requirement miss. The absent label views leave a different question open: whether the label is legible.
A diagram of the recorded requirement and result, not a scene render. Width can be measured from the USD. Legibility needs the caller's views. Neither question is answered by the 23 general-rule passes.
A separate test used a deliberately repaired panel: its width changed to 0.30 m, and its stored extent, the bounding box USD saves with a mesh, was updated to match. The check passed against the same approved scope, without another interpretation call. That is the behavior I want: repair the delivery against the requirement we agreed. Changing the policy or the check implementations needs a new scope review.
The interpreter did not always organize the same brief identically. A repeat grouped it into two requirements instead of three, while keeping the dimensions and separate-view requests. A conflicting brief with widths of 0.30 and 0.40 m produced no width target and needed review. I would resolve the conflicting dimensions, then review and keep the proposed scope before using it to accept a delivery.
The legibility questions stay open until someone renders the views. Rendering stays with the application that created or opened the scene: the harness asks for views, target parts, times and capture constraints, and the caller returns the images with a receipt tied to the scene revision, which means a repaired scene needs fresh images. Relabeling one panel image cannot satisfy both the front and rear requests, and even distinct images with matching metadata leave a reviewer to decide whether they show the requested surfaces.
Read a failure as a request for a particular next step
A failed dimension needs a repair. Missing front and rear views need captures. A disputed interpretation needs scope review. A crashed evaluator needs investigation. Sending all four back as “try generating the scene again” would waste attempts without necessarily resolving anything.
The report keeps those cases apart. Each finding carries a next_action, such as repair_scene, provide_evidence, review_specification or fix_environment, so application code can route it directly. The report also retains the scene revision, inventory, brief source, selected checks, subject counts and unresolved requirements.
If a repair round drops a check, the report shows that check as unassessed, so I can’t mistake a problem nobody measured again for one that was fixed.
From the brief to an acceptance decision
A brief can include more than written instructions. For a manufacturing scene, it could include a P&ID (piping and instrumentation diagram), layout, equipment list, datasheet excerpts and reference photos. The owner needs to say which sources are authoritative, which are only illustrative and which questions are still open.
The harness needs those requirements turned into something it can assess: a measurement with a target, a question for review, or a request for evidence. I call that agreed selection the acceptance scope. A requirement the available checks cannot answer stays visible as a gap.
Some checks come from general delivery rules, such as whether referenced files can be found. Others need the brief: the required width of a panel, when a part should arrive, or which side of a label must be readable. Without task requirements in a brief or a contract (the file of targets and tolerances the checks read), general checks cannot tell me whether the delivery meets my intended use.
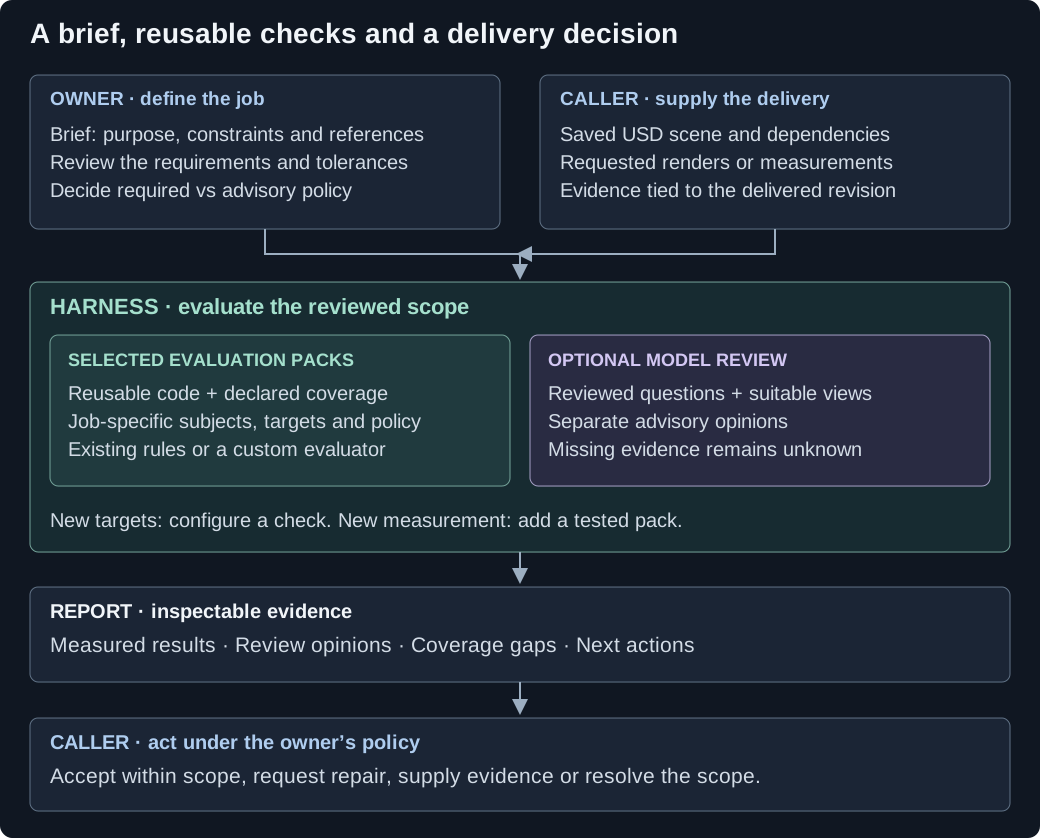
The owner decides what counts as acceptable for the job: the intended use, requirements, tolerances and tradeoffs, and the release policy, which says which decisions can be handled routinely and which need a person. The calling application, or caller, is the software or agent that receives the delivery. It saves the scene and brief, invokes the harness, supplies the renders or measurements the harness asks for, owns the rendering environment and repair loop, and acts on the result. The producer builds or repairs the scene, and the harness only checks and reports within the approved scope.
The workflow starts with that scope and a saved USD scene, the file format the harness reads. Reusable groups of checks, called evaluation packs, inspect the delivery. Where a question needs rendered views, the calling application supplies them for a person or an optional AI judge to inspect.
The owner defines the job; the calling application supplies the delivery and evidence. Reusable packs provide measurements, while each job supplies its subjects, targets and policy. An optional interpreter can propose the scope from a raw brief before this evaluation. Rendering and its GPU stay with the caller.
The interpreter and the judge have different jobs
The interpreter proposes what to check. The judge gives a qualitative opinion on the delivery against that scope and the supplied evidence. By default it does not see the script findings; the caller can choose to include them.
Scroll sideways for more columns.
Question
Script
Optional LLM/VLM judge
Input still needed
Does the delivery meet selected USD and file rules?
Reads composition, dependencies and selected mesh properties.
Cannot replace these measurements.
Application policy; no task brief required.
Are dimensions, placement or counts correct?
Compares named objects with targets or a baseline.
Can flag apparent layout concerns in suitable views.
Targets, reference points and tolerances from the brief or contract. Images are not precise metrology.
Is timing or motion correct?
Checks duration, sampled positions and named connection distances; the development package also bounds gaps for supported translation-only motion.
Can flag an apparent separation or sequence problem in timed views.
Required times and relationships. Sampled passes leave unobserved intervals open; continuous bounds require the supported motion model.
Does the texture meet the task?
Resolves bindings, decodes images and compares selected source pixels.
Reviews visible appearance or legibility in textured renders.
Reference/comparison policy for pixels; suitable views for appearance.
Does the simple incline model meet its displacement limit?
A CPU worker measures the fixed ramp-and-block model’s trace; the development package lists it as an example pack.
No physical-validation adapter; returns unknown.
Supported model, task limit and parameter evidence.
Does it satisfy an unstated preference?
No target to compare.
Can raise a question, but has no way to know what the owner left unsaid.
Clarification or an explicitly chosen default.
The calling application selects checks, judge or both; checks are the default. Judge-only leaves numerical content checks unassessed. In both mode, the report keeps measured PASS/FAIL separate from advisory consistent/concern/unknown, and a model opinion cannot override a required measurement failure. A repair that adds materials or motion needs a new scope covering them before the caller can accept the revised scene on that basis, as the application protocol explains.
In the panel’s no-image evaluation, the visual questions returned unknown without a judge call. A failed capture or model call also leaves completed script findings intact. I would rather have the width failure and an explicit request for views than lose a useful measurement because another component could not run.
Sorting the decisions a delivery leaves open
Script results can leave the producer’s choices open, as the transfer arm showed. The caller can declare those items next to the requirements: inferences the producer made and design decisions it disclosed, such as a tolerance it chose. The declared-scope review assesses that declared list under the owner’s policy, which marks each item required or advisory. Optional AI triage then recommends routine handling, human review or more context, citing evidence and possible consequences. The report places that recommendation beside the applied policy and any human decision.
Only a current human approval can close an item the owner’s policy marks for mandatory human review; the model cannot waive it or clear a required failure. The development package groups human review into low, medium and high risk, using definitions the owner can override. The grades set review priority for this job; an engineering safety rating would need its own assessment.
Two larger scene builds, a dairy and a distribution centre, put this workflow through actual repairs. One rejected a broken material binding; the other exposed a delivery policy missing from the brief and, through separate review, a route indicator showing the wrong state.
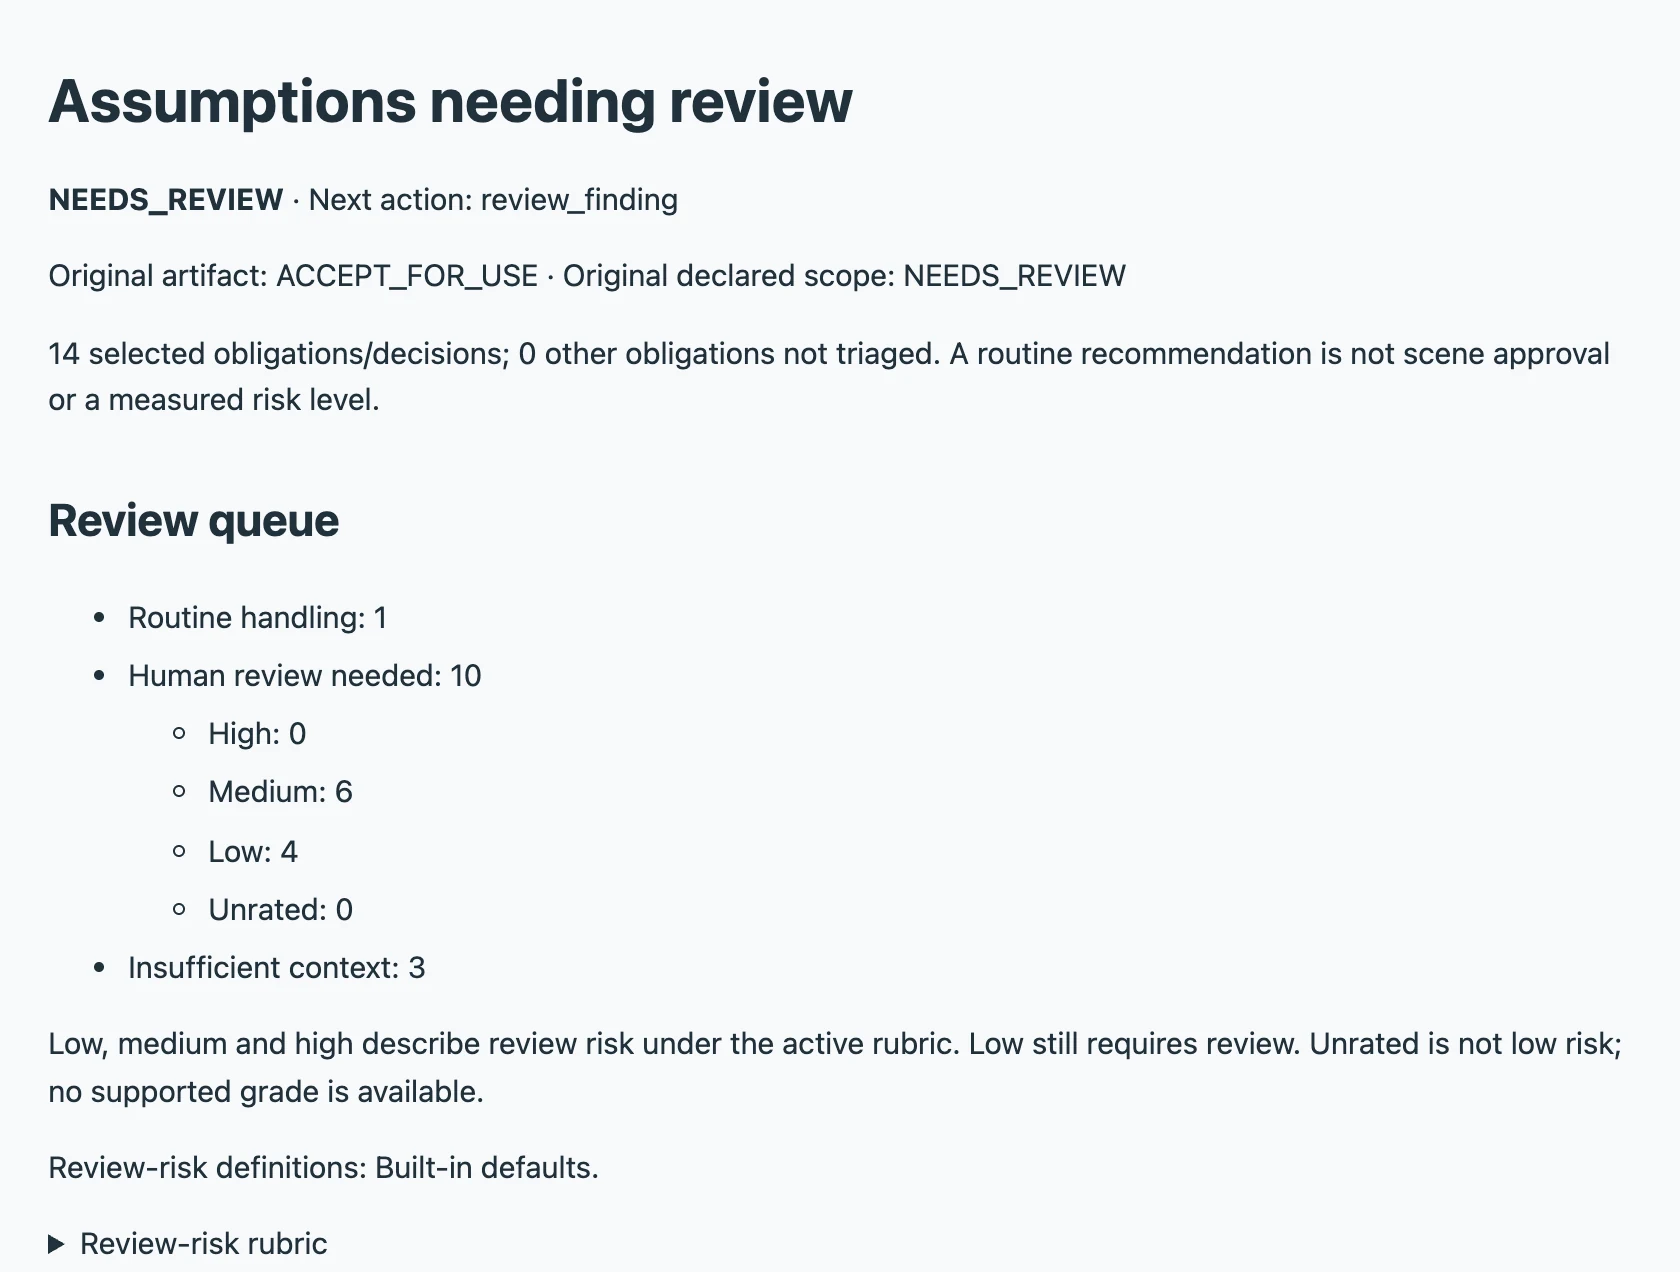
In a later check of the dairy delivery for layout and process explanation, the scripts reported 137 passing check rows and four additional rows with no applicable subjects, while seven declared requirements remained unresolved. Text triage then considered the brief, producer disclosures and assessment, without rendered views. It reviewed 14 selected declared items, a different set from those seven that included some whose checks had passed. Of those 14, the applied policy routed ten to human review, three to more context and one to routine handling.
The saved triage report groups work for review; these are not ten confirmed defects. Open the combined report for script results, brief coverage and AI recommendations, or go straight to the triage reasons.
The pipe-connection item shows why I want those layers visible. Its endpoint measurements passed, but they did not show contact with the visible nozzle geometry. For process explanation, pipes that appear disconnected could make the flow hard to follow. The report did not confirm that defect; it left the visible connection and the producer’s chosen tolerance for medium-priority review.
On three other items, the model suggested routine handling while listing missing context, and the policy kept all three open. No human triage decisions were recorded, so the delivery still needed review. A smaller runnable example supplies the files to try this workflow.
Triage only sees the declared items it receives. The experimental audit proposes cited questions about possible omissions, but I have not tested how reliably it finds the ones that matter.
I want the same review discipline on every delivery: agreed requirements, evidence from the saved result, named decisions and another check after repair. If I disagree with a recorded assumption, I can ask for evidence, narrow the intended use or change the requirement explicitly, and the next assessment then uses that agreed scope. The calling application turns this into a gate by requiring the scoped result and approvals before release; the harness cannot enforce that policy on its own.
What putting the harness to work taught me
A broader study varied how much detail the brief gave. It covered 24 first deliveries across three synthetic scene families (a gantry inspection cell, a rotary indexing bench and a pump/valve skid), four brief depths (a simple prompt, then light, medium and detailed briefs), and two attempts per condition, with no feedback or repair. Only the detailed brief supplied a 21-position motion path and an exact reference image. The study ran on an earlier development build. My coordinating assistant requested gpt-6-astra as the producer, with tools disabled; the service did not report the resolved model snapshot. The same assistant wrote the briefs and evaluated the scenes, so this was an exploratory exercise.
Scroll sideways for more columns.
What was assessed
What happened
What I take from it
General delivery policy
21 of 24 scenes were rejected for missing stored extents or authored normals.
State the delivery policy in the brief when the producer is expected to meet it.
Supplied geometry and motion rules
All selected rules passed. Five of six medium-brief scenes differed from a fuller path they had not been given.
Separate a missed requirement from a target the producer never received.
Exact source images in detailed briefs
Five of six deliveries differed from the supplied reference.
More detail did not remove the need to check the saved result.
Denser motion samples
All six detailed paths passed at 21 and 201 checkpoints.
This exercise found no hidden path defect; more samples remain finite coverage.
Optional visual judge
Follow-up inspection established no additional scene defect.
Better views and reviewed known cases are needed to assess added detection value.
The judge’s two apparent cable-gap concerns were not confirmed by source inspection. Its motion concern matched an existing comparison against the fuller path that the producer had never received. The scene records are not published, but the study protocol and judge results give the conditions and outcomes. Constructed motion controls and a later rendered-sign test expose particular gaps separately; they are not additional defects in these 24 deliveries.
When I would take on the extra machinery
In an earlier comparison, a small script matched the first version of the harness on the same 18 static-cube cases within their shared scope, covering the requested edit and layout constraints. This was a comparison of geometric decisions, not a demonstration of less review work. For one stable conversion or edit, I would start there. Packs and a common report become useful when different jobs need different requirements, and the caller needs to tell a failed measurement from missing evidence without learning each evaluator’s output format.
Existing OpenUSD validators already provide useful checks of scene files. Where a SimReady profile, one of NVIDIA’s requirement sets for simulation-ready assets, fits the job, I would use its validation and runtime tests within this workflow. I want those findings beside the brief and the other evidence the job needs, so I can decide what needs to happen next. The development package can import selected engine results through a bridge the caller configures; that bridge has not yet been tested against a real SimReady installation.
I started with the checks my own 3D jobs needed, so the depth varies across geometry, materials, motion, rendered views and simulation. For someone else’s brief, I would map each requirement to an existing check, a review question or an open evidence need; a new tolerance usually changes only the contract’s parameters, while a new measurement needs a pack such as the polygon-budget example. The adopter guide walks through those choices.
I have not yet measured whether any of this saves work. The next comparison needs an independently supplied brief and external assessment, and I would count time, compute and human review per accepted result against a competent script-and-review workflow, including the unsuccessful attempts. Triage has the same open question: the ten-case pilot needs a domain reviewer to mark which items matter for the stated use before seeing the model’s answers, and those labels are still pending.
Show the v0.3.0 install steps and the tray example
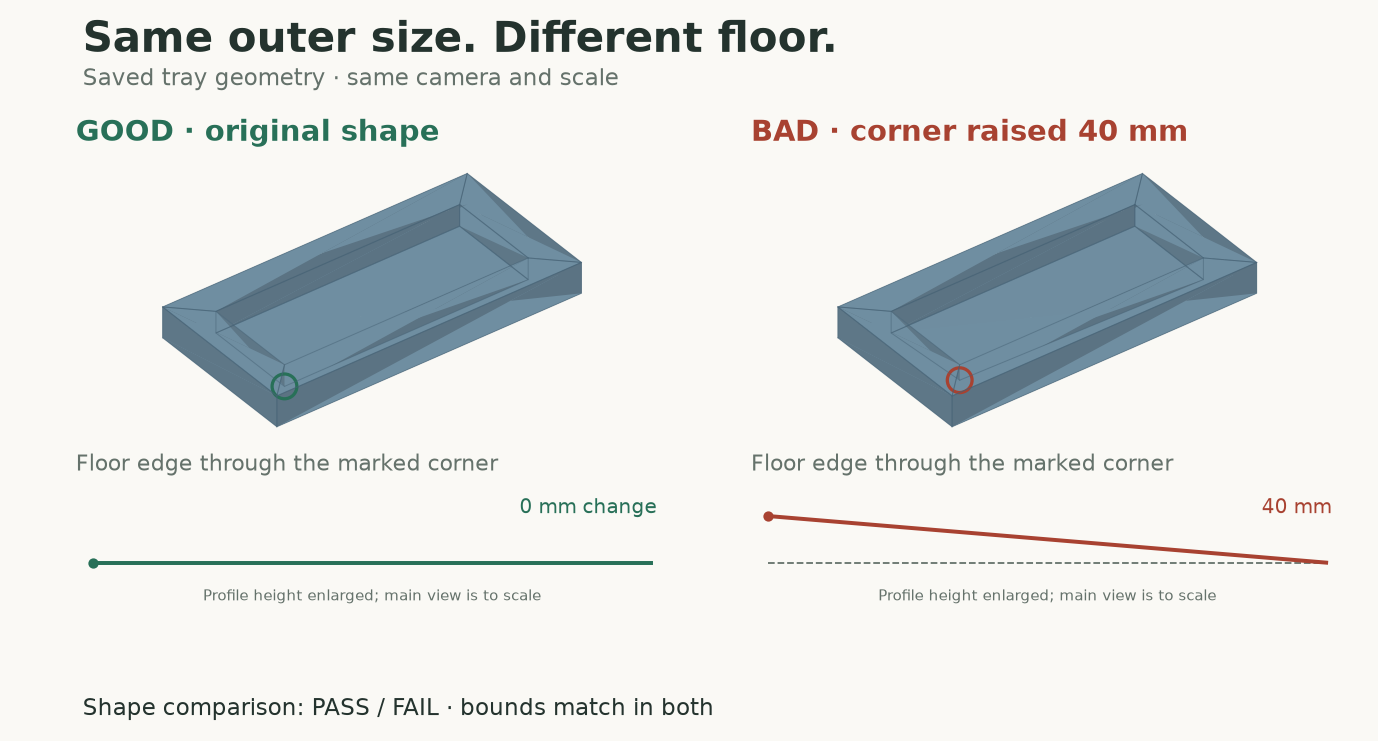
The original v0.3 release provides a smaller reproducible test of the same acceptance idea. A translation-only task requires the tray to reach a destination while preserving its mesh. In the failing fixture, one interior floor point has moved 40 mm. The requested center and outer dimensions still match; six checks pass and shape preservation fails.
Both versions have the requested position and outer size. Comparing the saved mesh with the original catches the changed interior point. These views come from the USD fixtures; only the profile height is enlarged. The defect was deliberately constructed to test the evaluator.
That shape rule compares connectivity and corresponding points after removing translation. It suits a task that keeps the original representation. A valid remeshing or reindexing would fail it, so I would not use the same rule for an edit that permits those changes.
Download and extract the v0.3.0 source and evidence release. The pinned replay was tested with Python 3.12 on macOS arm64. From the extracted folder:
The expected result is REJECT, with exit code 2. Open /tmp/tray-check-01/report.html or inspect result.json. Choose a new output directory on each run; the CLI refuses to overwrite one or put it inside the input bundle. Relative scene and contract paths are resolved within --bundle-root.
The replay uses OpenUSD 25.11 for scene reading and measurements, JSON Schema 4.25.1 for contracts and optional NVIDIA USD Validation 1.20.0 for selected upstream rules. The material, motion and physics articles each keep their own versioned replay, and the pack API carries the extension reference.
The tray example in that release checks a static part. The Astra crank-slider, an animated assembly an agent built, needed separate measurements of its linkage, and passing the tray check would say nothing about its moving attachments.
For a new integration, the caller passes a saved local USD bundle through check-3d-app or the Python library; the application protocol documents both, and the README explains which installation has which capabilities. Installed packs run trusted Python. Release 0.6.0 has a fixed limit of 10,000 prims. In the development package, the caller can raise that default budget; admitting more objects does not establish that a particular large scene has been validated.
Optional brief preparation and capture limits
If requirements are already mapped to checks, scripts can run without an LLM. For a raw brief, an optional interpreter proposes that mapping and the views to request, and the caller reviews the proposal before using it to accept a scene. I call that proposal step preparation. Sources can be text and images; the unreleased development package also accepts selected PDF pages or regions. A P&ID can go in as reference material, but the harness has no automatic P&ID understanding, so the connections the interpreter pulls from it go through the same scope review as everything else.
In the development package, preparation also checks whether the capture plan can run. In a replay of a saved interpretation, the view plan, the list of renders the harness would ask the caller for, asked for 13 captures when the capture budget allowed eight. Preparation keeps that plan visible but asks the caller to revise it before capture. A ready plan still needs scope approval.
What I want before accepting the delivery
For the press-shop arm, I would make constant link length part of the agreed requirement and ask for evidence through the motion. The retained arm example shows my visual finding and the repair; it does not demonstrate a harness detecting that shortening. The panel test shows what the report can already separate: a measured width failure, missing views and a scope decision. Before accepting a delivery, I want each of those resolved for the job it is meant to do.
Disclaimer: The views and opinions expressed in this account are those of my own and do not represent those of my employer, NVIDIA.